World Models
Models that learn how an environment responds to actions, then plan or train agents inside it: model-based RL, Dreamer, MuZero, Genie, world foundation models, and JEPA-style planning.
Before this: Reinforcement Learning and Generative AI: Images & Video. Self-Supervised & Contrastive Learning helps for the JEPA steps.
-
 29 min
Step 1
What world models are
The core idea: a learned model that predicts how a world changes after an action.
But what exactly are world models?Julia Turc
-
 18 min
Step 2
Model-based reinforcement learning
Learn a dynamics model from experience, then use it to plan or improve a policy.
L6 Model-based RL (Foundations of Deep RL Series)Pieter Abbeel
-
 19 min
Step 3
World Models (Ha and Schmidhuber, 2018)
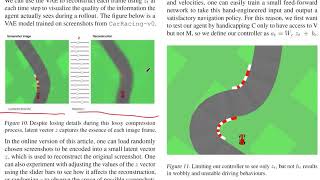
A VAE compresses frames, an RNN predicts the next latent, a tiny controller acts.
World ModelsYannic Kilcher
ctallec/world-models★ 721 -
 55 min
Step 4
Dreamer: learn behaviour inside the model
DreamerV2 trains its actor and critic on imagined latent rollouts, mastering Atari.
Dreamer v2: Mastering Atari with Discrete World Models (Machine Learning Research Paper Explained)Yannic Kilcher
danijar/dreamerv2★ 1.1k -
 34 min
Step 5
MuZero: plan with a learned model
Its author explains a model that predicts reward, value, and policy, not pixels.
MuZero - ICAPS 2020Julian Schrittwieser
werner-duvaud/muzero-general★ 2.9k -
 1h 01m
Step 6
Genie: worlds you can walk through
The Genie 3 team on generating frames in real time from a user's actions.
Genie 3: An infinite world model | Shlomi Fruchter and Jack Parker-HolderGoogle DeepMind
-
 13 min
Step 7
World foundation models
Large video-trained models used to generate training data and test robots and cars.
World Foundation Models - ComputerphileComputerphile
-
 36 min
Step 8
NVIDIA Cosmos, an overview
NVIDIA's GTC 2025 introduction to its open world foundation model platform.
An Introduction to NVIDIA Cosmos World Foundational Models | NVIDIA GTC 2025NVIDIA Developer
-
 59 min
Step 9
Predict in representation space: LeCun's case
Why LeCun argues world models should predict abstract features, not every pixel.
Yann LeCun: World Models: Enabling the next AI revolutionComputer Vision and Geometry Group, ETH Zurich
-
 44 min
Step 10
V-JEPA 2: plan robot actions
A self-supervised video model gets an action-conditioned predictor for robot planning.
Introduction to World Models: V-JEPA 2YanAITalk
facebookresearch/vjepa2★ 4.9k
Build it
Watching isn't learning. Pick one and put it on GitHub.
- Recreate the 2018 World Models pipeline on CarRacing: train the VAE, the next-latent RNN, and a small controller, and compare a policy trained in the dream with one trained on real frames.
- Train muzero-general on a small game such as tic-tac-toe or CartPole, then plot how often its learned-model rollouts predict the true reward a few steps ahead.
- Learn a dynamics model for a Gymnasium environment from random play, then use it for model-predictive control and compare reward against a model-free baseline.